Skip to content
← About BrisAI
Technical portfolio · Founder, BrisAI

Art
Wieczorkowski.

Software and machine-learning engineer. I build systems across the boundary between research and working software — and show the architecture, the evidence and the limits behind each one.

01

Individual MEng project / 2026 / Reinforcement learning

Learning to share the load.

LLM-assisted multi-agent learning for edge-network resource management

Built
A five-node packet simulator and MARL training environment
Owned
Simulation, bridge, environment and reward-shaping experiments
Hard part
A stable reset/step contract across Simulink and EPyMARL
Evidence
Award-winning MEng project with public source and setup
Inside the edge-network simulationDissertation / Figures 3.2–3.5

Follow a task through the system.

Select an edge node to inspect its processing and offload paths, or explore how the agents learn.

Bidirectional five-node ring: A, B, C, D and EEach edge server exchanges tasks with its two neighbours. Highlighted links connect the selected server to both possible offload destinations.Ring topologyTwo neighbours per server

Lines: neighbour links · Highlight: selected node’s links
Labels: configured processing rates in the base network (Table 3.1).

Edge A / task routing

Incoming tasks

Newly generated tasks, or tasks from E and B

Decision controller

Applies the agent’s offload probability and routing safety rules.

Local processingFIFO queue → Edge server → Completed

Tasks wait in arrival order, then process at 69,000 bit/s.

Offload to E or BLink delay → Neighbour’s controller

A heuristic selects between both neighbours using processing rates and link delays.

DropOverload protection → Task removed

The controller drops an arriving task when the overload safety condition is met.

One-hop limit: an already-offloaded task must be processed locally, unless the overload rule drops it.

Explanatory reconstruction of the dissertation’s network and node subsystem (§3.2, Figures 3.2–3.3), environment interface and MARL architecture (§§3.4–3.5). Values are configuration, not live telemetry. Offload percentages represent probabilities for eligible tasks, not guaranteed traffic shares.

The problem

Each edge node can process incoming packets or offload them to its neighbour. Moving work out of one queue can overload the next. I modelled this as a cooperative, partially observable decision problem: five agents, local observations, and a shared reward for reducing latency and packet drops.

What I found

IQL was more consistent on the simpler network; QMIX became more useful when heterogeneous processing rates and queue capacities made coordination matter. The dissertation’s detailed comparisons focus on IQL, QMIX and a random baseline.

The LLM rates network states and contributes an auxiliary learning signal. Its effect depended on prompting, weighting and agent masking. The complex-network results were inconclusive: the best shaped run matched the best QMIX return, without establishing a general improvement.

Implementation & experimental limits

The Python environment exposes reset and step operations through the MATLAB Engine API. Each agent chooses from five offload levels: 0%, 25%, 50%, 75% or 100%. EPyMARL also has VDN, IPPO and MAPPO configurations in the public repository.

This is an abstract packet simulation, with a small number of experimental seeds. Training time constrained the search over LLM prompts and settings. Findings are from dissertation §§4.2–4.5; they do not establish performance on a physical edge network.
02

Independent project / Signal processing + security

Listening for an intrusion.

Unsupervised network anomaly detection with spectral features

Built
An end-to-end, window-level anomaly-detection pipeline
Owned
Features, model comparison, tuning, tests and documentation
Hard part
Separating representation gains from detector gains
Evidence
ECOD AUROC 0.954 vs 0.794 on the same evaluated split
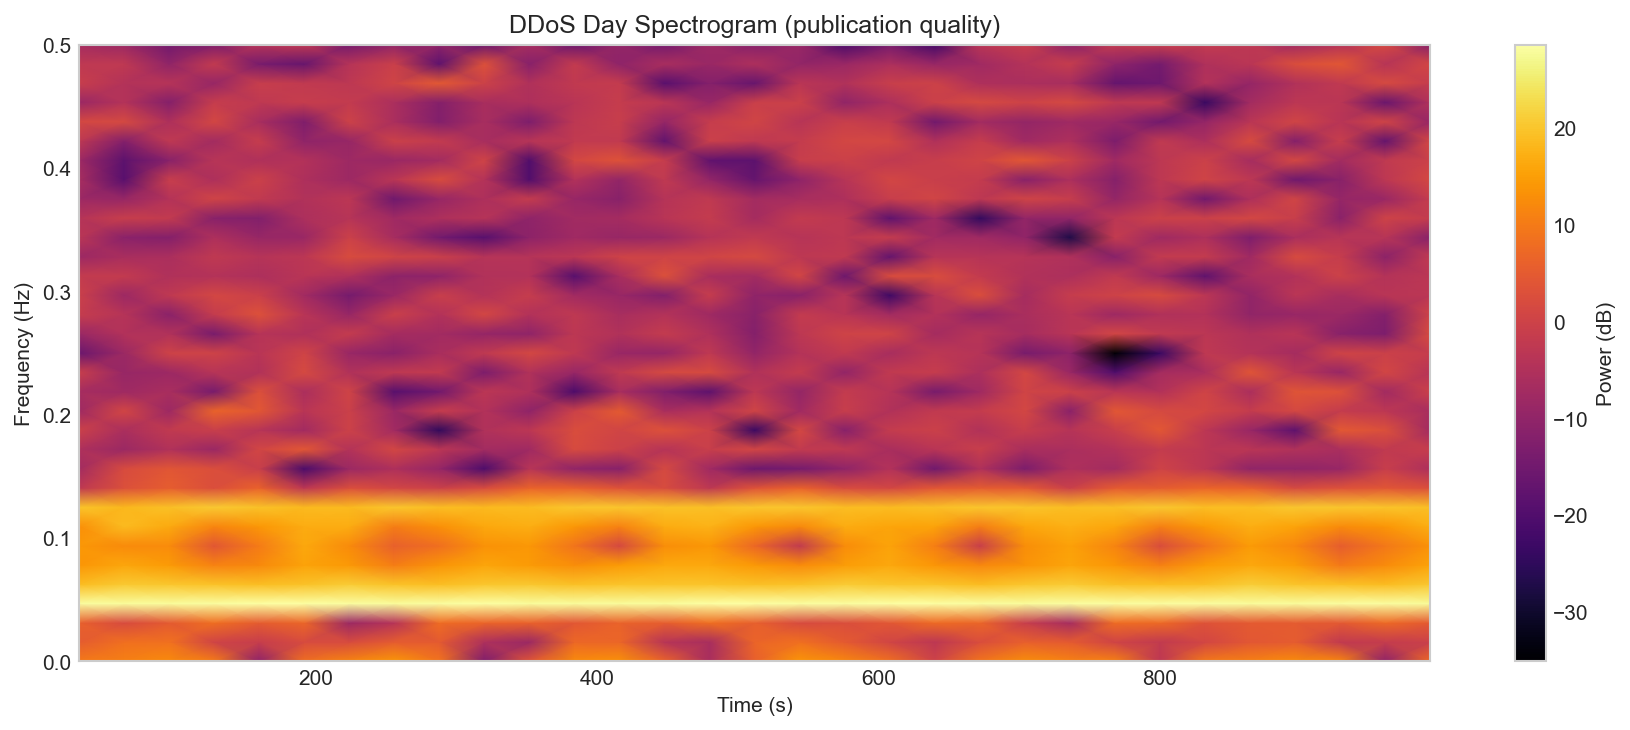
Frequency-domain viewCICIDS2017 / DDoS
DDoS spectrogram showing power by time and frequency, with bright low-frequency bands around 0.05 and 0.12 Hz.
Repository spectrogram: brighter colours indicate greater spectral power. The project constructs its time axis from flow order; the seconds shown are synthetic, not verified capture timestamps. Original figure
0.956Ensemble AUROC
0.869Ensemble AUPRC
0.954 vs 0.794ECOD AUROC: spectral vs raw aggregates

Reported repository results · majority-labelled windows · Friday attacks + held-out Monday benign traffic. Evaluation protocol & tables

Why spectral data?

A sequence of network flows contains structure that a single record misses. I aggregate bytes, packets and duration into windows, apply a Hann-windowed FFT, and describe the resulting spectrum using features such as entropy, centroid and flatness.

On the evaluated split, ECOD with spectral features achieved 0.954 AUROC, compared with 0.794 using window-aggregated raw flow features. That comparison is the useful result: the representation made a measurable difference with the same detector and split.

What the score covers

The tuned ensemble combines ECOD (75%) and Isolation Forest (25%). Models train on benign Monday traffic; labels are used for validation, tuning and evaluation. The headline result labels a window as an attack when at least half its flows are malicious, focusing on DDoS and PortScan.

Pipeline & failure cases

The fast branch uses 64-second windows with 50% overlap, alongside a 256-second slow branch. RobustScaler is fitted on benign training windows. Six model families are implemented; validation selects the ensemble weights.

Under the stricter “any attack flow” rule, ensemble AUROC falls to 0.877 overall and 0.365 for Bot traffic. Low-volume command-and-control is a clear failure case. Synthetic timestamps also limit conclusions about real traffic periodicity. These are reported repository results, not a new evaluation run.

03

BEng group project / University of Bristol / 2025

From a dataset to a hospital LAN.

Deployable machine-learning intrusion detection in a virtual network

Built
An inline ML intrusion detector in a virtual hospital LAN
Owned
Virtual lab and algorithm and simulation-performance work
Hard part
Reconciling offline features with a live traffic extractor
Evidence
LightGBM reached 0.85 F1 in the small integrated test
The experimental networkGNS3 + VMware
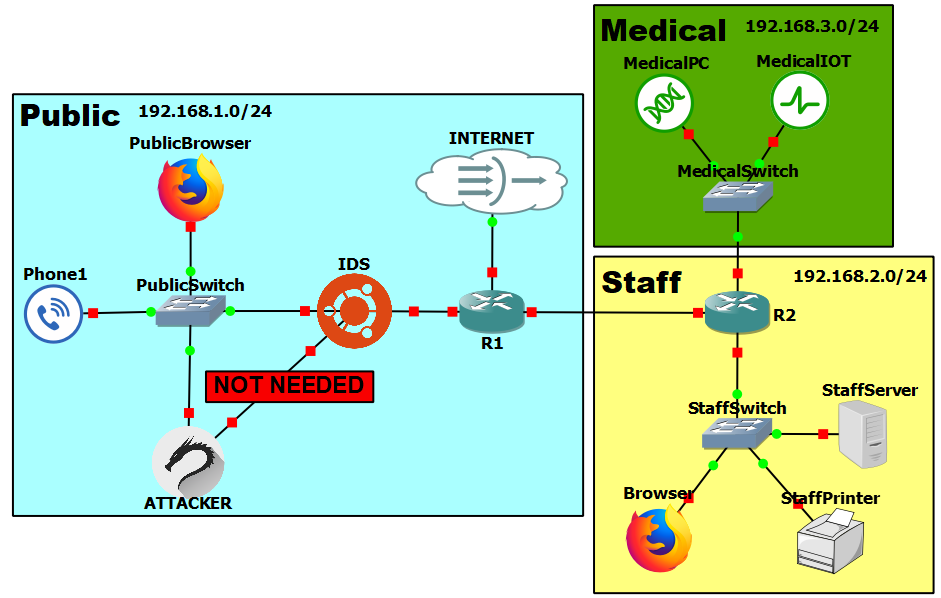
GNS3 hospital LAN with public, staff and medical subnets. An Ubuntu IDS bridges the public switch and router; Kali Linux supplies attack traffic.
Figure 25 from the group report: the implemented network, with separate public, staff and medical subnets. Group report

What we built

We trained and compared seven models on KDD Cup 1999, then integrated supervised classifiers with a feature extractor and an IDS script inside a simulated hospital LAN. The IDS ran as an inline bridge, inspecting traffic passing between the public subnet and its router.

The result that mattered

XGBoost led on the test dataset, but LightGBM performed best in the virtual network: the report records 0.74 accuracy, 0.96 recall and 0.85 F1 (Table 8). The simulation used 24 connections per class across normal traffic, DoS, R2L and probing.

The change in ranking exposed the gap between offline classification and an integrated system. Live feature extraction lacked some training features, including “logged_in”, while background traffic introduced additional noise.

Attribution & limitations

Group: Younis Hubsey, Billy Usher, Katie Vandrill, Zhiling Wang and Art Wieczorkowski. Contribution attribution follows the report’s section headings (§§4, 5 and 7).

KDD Cup 1999 is dated and imbalanced. This was a small virtual-lab evaluation, not a clinical deployment. Unsupervised models were evaluated offline but were not tested in the simulation because integration remained unfinished.

04

BrisAI / In-house evaluation / Applied software

Testing the system, not the demo.

Four pre-registered held-out evaluations of an AI-assisted Outlook inbox sorter

Built
An Outlook classifier with durable decisions and review paths
Owned
Workflow, safety boundaries, evaluation harness and documentation
Hard part
Knowing when to route, abstain or surface uncertainty
Evidence
4 pre-registered runs; 250 held-out items × 3 repeats; both gates met
The implemented control pathSmart Inbox / frozen evaluation
  1. 01 / InputRead

    Sender, subject and capped body preview

  2. 02 / ModelScore

    Rank five permitted business categories

  3. 03 / CodeBound

    Apply threshold, schema and permission rules

  4. 04 / ReviewRecord

    Keep decisions, failures and borderline cases

The model proposes scores; ordinary code restricts the action. The workflow can label mail in place, but cannot move, delete, reply to, forward or mark a message as read.
158 / 165Messages filed automatically, filed correctly
0High-severity errors, and 0 of 750 calls failed
21 / 21Automated safety-boundary checks passed

Held-out synthetic evaluation at a declared operating mix · blind-adjudicated · no client data. The result describes this test, not a real mailbox.

The finding to lead with

The first pre-registered run found a working prompt injection in my own system: an instruction embedded inside one supplier-statement email chose both the route and the confidence score, in all three repeats. Fencing the untrusted content fixed it; measured afterwards on 26 scored injection items, nothing was routed to the category an injection demanded.

The third run then falsified a prediction I had published in advance, and exposed that the change had silently disabled a safety rule. I published that run. The fourth repaired the rule and met both readiness gates jointly — precision at or above 95% and coverage at or above 70% — on a set it was not designed from.

Evaluation limits & engineering response

The 250 synthetic items were adjudicated blind and frozen before scoring, at a declared rather than measured operating mix. There was no human, rules-based or alternative-model baseline, and the system author was not independent of the evaluation.

The costs are published beside the result: a sender rule that caught no fraud on this set and held twelve legitimate invoices, two personal messages filed as marketing, and one message in eighteen changing category between identical runs. No frozen set is reused to claim improved performance after a change.

05

BrisAI / brisai.co.uk / Web engineering + operations

Shipping the thing you are reading.

A launch-gated marketing site with two proven intake pipelines, built and operated end to end

Built
Next.js 16 / React 19 / TypeScript site with a WebGL hero, an interactive assessment and two intake APIs
Owned
Design system, front end, API routes, durable email delivery, test suites, privacy engineering, DNS and email cutover
Hard part
Proving delivery instead of assuming it: idempotent retries, ack-then-fail alerts, real-host verification
Evidence
11 of 11 launch suites green; 0 accessibility violations on 19 routes; SPF, DKIM and DMARC aligned
26prerendered routes
3API routes behind Turnstile + rate limits
11 / 11launch suites passing
0axe violations · 19 routes × 2 viewports

Figures from the 14 September 2026 launch run and the site’s own configuration. The source repository is private; the live site, its runbook and the recorded check results are the evidence.

How it is built

Pages prerender at build time; API routes run as serverless functions in Paris. Each intake route verifies a Cloudflare Turnstile token, validates against a shared zod schema, and re-scores the assessment on the server. Submissions and email jobs are recorded atomically in Postgres, then sent through Microsoft Graph. Client-held retry keys prevent ordinary retries from creating duplicate work; uncertain email sends require human review.

Proving it works

A launch runner builds the site, starts its own production server on an isolated port and refuses to run if anything else answers there, then runs eleven suites: type checks, scoring scenarios, claim-consistency and workflow-exhibit checks, enquiry and Snapshot integration against local mocks, a WebGL scene suite, axe accessibility across nineteen routes at two viewports, buyer-trust invariants, visitor journeys and the guided demonstrations. Every result is written to a file that the release record cites.

Operating it honestly

The privacy notice renders its list of processors from a typed data file, so adding a provider to the pipeline is the same change as disclosing it. A data-flow inventory records every store, region and deletion path, and the launch runbook recorded each hosted proof — webhook rejection without the secret, rate limits with a spoofed forwarded header, an alert when a report fails after the visitor was told it was on its way — before the domain moved.

Limits & what this does not claim

This is a brochure site with two forms, not a high-traffic application; the figures above describe the launch checks, not production load or conversion. Rate limiting is per serverless instance plus a platform rule, not a distributed limiter. The content-security policy permits inline scripts to keep static generation. A scheduled task deletes intake database records after thirty days; mailbox records are reviewed separately. Email acceptance does not prove inbox delivery. The source is private, so the evidence is what the live site does and what the runbook records.

Range

What I reach for, and where it has been used.

Grouped by kind rather than by keyword. Each group names the project on this page or the part of this site where the tools did real work.

Languages

Written for real projects

  • Python
  • TypeScript
  • JavaScript
  • MATLAB
  • C
  • C++
  • Java
  • Go
  • Haskell
  • C#

Python across all four research projects; TypeScript throughout this site; the rest in university and personal work.

AI & data

Learning systems, evaluated

  • Supervised & unsupervised ML
  • Multi-agent RL (EPyMARL)
  • LLM workflows & prompt design
  • Structured output validation
  • Evaluation harnesses
  • Signal processing (FFT)

Projects 01–04: MARL at the edge, spectral anomaly detection, the healthcare IDS and the pre-registered Smart Inbox evaluations.

Systems & security

Networks, simulation, hardening

  • Simulink & SimEvents
  • Wireshark · Kali Linux
  • GNS3 · VMware
  • Cisco networking concepts
  • CSP · HSTS · rate limiting
  • Bot verification (Turnstile)
  • SPF · DKIM · DMARC

The five-node edge simulator, the virtual hospital LAN, and the protection layer on this site’s intake routes.

Product & web

Shipped, monitored, documented

  • Next.js · React
  • Tailwind CSS
  • three.js / WebGL
  • n8n workflows
  • Microsoft 365 · HubSpot APIs
  • Vercel · DNS · email auth
  • Puppeteer & axe test suites

Project 05: brisai.co.uk, from the WebGL hero to the DNS cutover and the eleven-suite launch runner.

Background

Outside the projects.

Alongside research and development, I’ve taught programming and worked on practical hardware and software troubleshooting.

  1. 2021–2026

    Computer Science and Electronics MEng

    University of Bristol · Upper Second-Class Honours (2:1).

  2. 2026

    Best Enterprise Master’s Computer Science Project

    Award sponsored by HP.

  3. 2026

    Inspiring Student Award

    Sponsored by the University of Bristol School of Electrical Engineering.

  4. 2024–2026

    Coding Tutor

    Delivered at least twelve sessions to three learners across programming, debugging and structured problem-solving.

  5. 2023–2026

    PC Repair Clinic

    Diagnosed dozens of hardware and software cases and translated fixes into accessible guidance.

  6. 2022–2024

    Digital Assistant · Von-Rohde Solutions

    Translated technical and non-technical requirements into organised, practical next steps.

Interested in the engineering behind the work?

Bring a business challenge, an application idea or a technical question. BrisAI can help explore the approach and build the system around it.